CodingOpen-sourceQwen 3.8Claude
Qwen3.8 family is my new favourite
95% Útil5% No útil
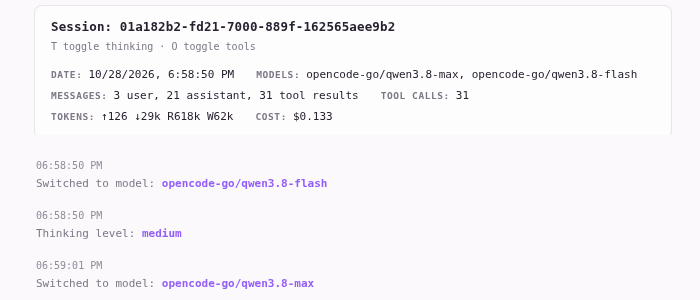
I ran one real build in ohmypi (omp): qwen3.8-max as the orchestrator, qwen3.8-flash as the executor. Below is what happened in that session, with the numbers the session recorded. My comparison with Claude is a general impression, not something this single run measured.
Model tested
- Model: qwen3.8-max (planning/orchestration) and qwen3.8-flash (execution), via ohmypi (omp). The session lists them as opencode-go/qwen3.8-max and opencode-go/qwen3.8-flash.
- Use case: coding - a planner/executor split on a small Python CLI
Prompts I used
Prompt 1, to qwen3.8-max (verbatim):
You are the orchestrator. Do not write code, create files or run commands. Produce an implementation plan for a separate executor model.

Project: build a Python 3 CLI tool, merge_csv.py, inside a new folder called dedupe-csv. Standard library only, no network or extra packages.

Requirements:
- Usage: python merge_csv.py INPUT_DIR OUTPUT_FILE
- Read .csv files in alphabetical order. Exclude OUTPUT_FILE from the inputs so reruns don't ingest their own output.
- The first non-empty file establishes the header. Skip files with different headers and print a warning naming each skipped file.
- Rows are duplicates when every column matches after trimming surrounding whitespace and ignoring case. Keep the first row's original values.
- Handle quoted commas and Unicode correctly.
- For an empty input folder, exit successfully with a clear message and no output file.
- Print files merged, files skipped, data rows read from matching-header files, and duplicates dropped.

Deliverables for the executor: merge_csv.py, test_merge_csv.py using unittest, a short README, and sample CSVs in samples/.

Produce an executor-ready plan containing:
1. Small numbered implementation steps. For each: files touched, what to implement, dependencies on earlier steps, and how to verify it.
2. Concrete test fixtures and expected outputs, worked out from the requirements. Cover cross-file duplicates, case/whitespace differences, mismatched headers, an empty folder, quoted commas, Unicode, deterministic ordering and rerunning with the output inside the input folder.
3. Any unresolved edge cases and your chosen behaviour, so the executor doesn't have to guess.
4. Exact commands the executor should run for tests and a sample CLI demonstration. Clearly label expected results as expectations, not observed results.
5. A final acceptance checklist and a review step to look for a missed edge case, add a regression test if needed, and rerun all tests.

Keep the plan practical and specific. Output only the plan, without implementing it.
Prompt 2, to qwen3.8-max: output this in plans/ directory
Prompt 3, to qwen3.8-flash (after switching models): execute the plan now
Tasks & results
Task 1 - Planning / orchestration (qwen3.8-max)
- Input: the planning prompt above. No code, no commands, plan only.
- Output: a 15.7 KB plan in about two minutes. It had 10 ordered steps with files, dependencies and a check for each, 8 test fixtures (F1-F8), 12 edge-case decisions made up front (E1-E12), exact commands, and an acceptance checklist. It was written to
plans/merge-csv-plan.mdwhen I asked. Max used 3 turns and 8,935 output tokens. - Where it slipped: the plan's expected numbers for "data rows read" were wrong in two fixtures (it said 5 and 3, the requirement gives 6 and 4). It also ordered the sample files so the bad-header file sorted first.
Task 2 - Execution (qwen3.8-flash)
- Input:
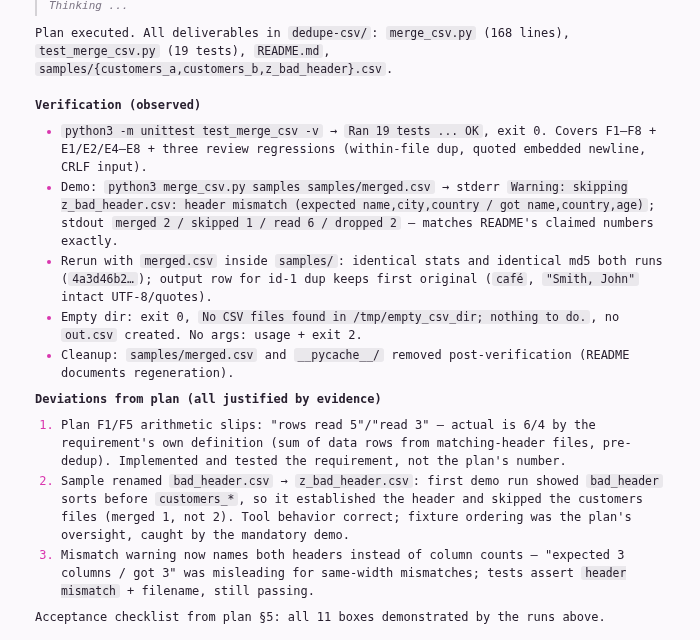
execute the plan now, with flash selected. It ran about six minutes, 18 turns and 30 tool calls (31 in the whole session). - Output:
merge_csv.py(168 lines),test_merge_csv.py, a README and three sample CSVs. The first test run was 16 tests with 2 failures and 1 error. One failure came from the plan's wrong row count. Flash checked it against the requirement, fixed the test, and did not copy the plan's number. The other two were a bug in its own test helper and a blank-line fixture, both fixed in the next edit. - The first demo run merged 1 file instead of 2. The bad-header sample sorted before the customer files, so it set the header and the good files got skipped. Flash saw it, renamed the file to
z_bad_header.csvand reran. It also changed the mismatch warning from "expected 3 columns / got 3" to naming both headers, because the old text made no sense for two files with the same column count. - Review pass: it added 3 regression tests (duplicates within one file, quoted embedded newline, CRLF input). Final run: 19 tests, all passing. Demo output: 2 files merged, 1 skipped, 6 rows read, 2 duplicates dropped. Rerunning with the output file inside the input folder gave the same stats and the same md5 both times. An empty folder exited 0 with a clear message and no output file.
- One small stumble: a todo call used a garbled task name and errored once. It retried and moved on.
Cost
These are the totals omp recorded for the session. Cost per category is the sum of the per-turn figures in the session file.
| Item | Cost |
|---|---|
| Input tokens (126, uncached) | $0.0001 |
| Output tokens (28,789) | $0.0629 |
| Cache read (617,750 tokens) | $0.0153 |
| Cache write (61,747 tokens) | $0.0543 |
| Total | $0.1326 |
By model:
| Model | Turns | Output tokens | Cost |
|---|---|---|---|
| qwen3.8-max | 3 | 8,935 | $0.1050 |
| qwen3.8-flash | 18 | 19,854 | $0.0276 |
Max cost about 79% of the total on 3 turns. Flash did 18 turns and cost about a quarter of max.
My honest verdict
- What impressed me: the split did its job on a real task. Max's plan was detailed enough that flash built the tool, a 19-test suite and a README in the same session for about $0.13, roughly 10 minutes end to end. Flash did not follow the plan blindly. When a test disagreed with the plan's arithmetic, it went back to the requirement, and it caught the sample-ordering problem by running the demo. The orchestrator and executor setup in omp worked as I wanted it to.
- What fell short: max's plan had two wrong expected numbers and a sample-file ordering mistake, and flash had to catch both. Flash's first test run also had 3 failing tests, one from a bug in its own helper. The final checks passed, but the plan was not clean on first write.
- Worth it? Yes - because a tool with 19 passing tests came out of this setup for $0.13, and the plan mistakes were caught by running the code, not by me. This is one small Python task, so I am not claiming it beats anything in general. My overall impression is that qwen3.8 max and flash through omp are as good as Claude for how I work, but this session did not test that, and I did not check the code line by line.